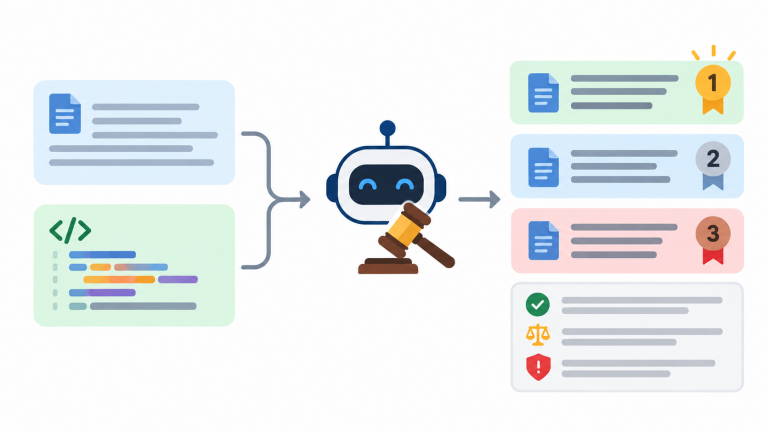
Large language models as judges: recent advances in LLM-based evaluation, critique, preference modeling, and feedback for text and code (2026)

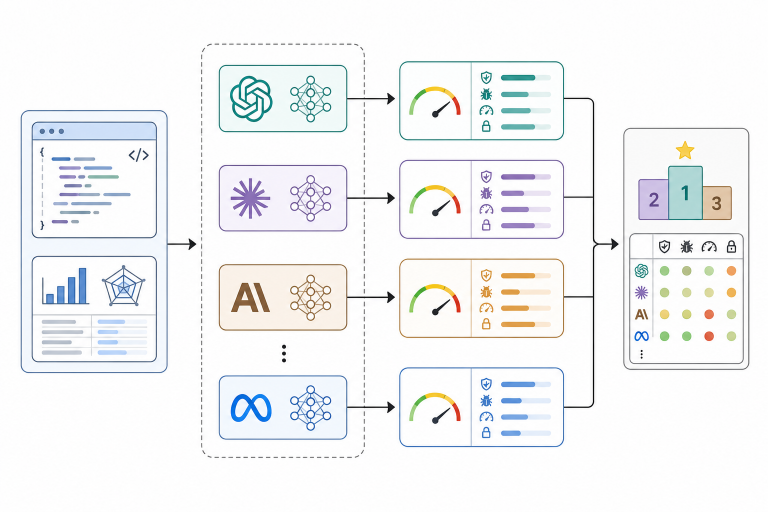
Artificial Intelligence Review Authors M. Nadăş Abstract Large Language Models (LLMs) are increasingly used as judges to evaluate, rank, and critique AI-generated text and code. This survey provides a comprehensive overview of recent advances (2020–early 2026) in LLM-based evaluation, covering techniques, applications, and challenges across domains. We make three main contributions: (1) a unified…
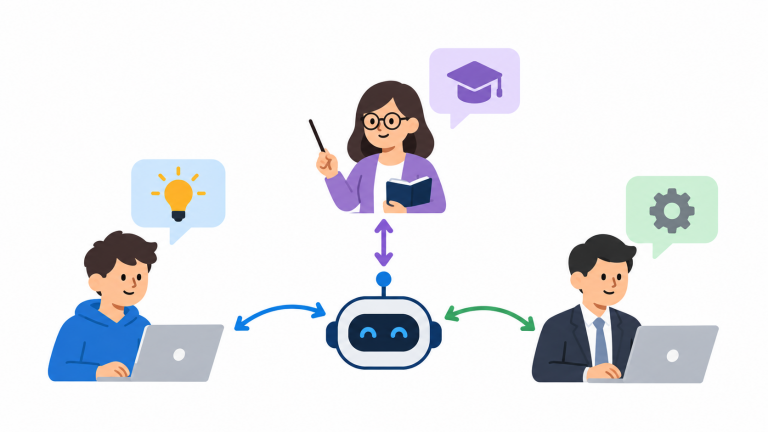
Generative AI in Computer Science Education: Insights from an Exploratory Study of Students, Educators, and Industry Professionals (2026)

International Conference on Computer Supported Education Authors L. Cernau, L. Diosan, Camelia Serban Abstract This study offers preliminary insights into the adoption of Generative Artificial Intelligence (GenAI) tools in computer science (CS) education, drawing on responses from 202 university-level computer science students, 16 educators, and 6 industry professionals. Employing a three-dimensional approach, the study…

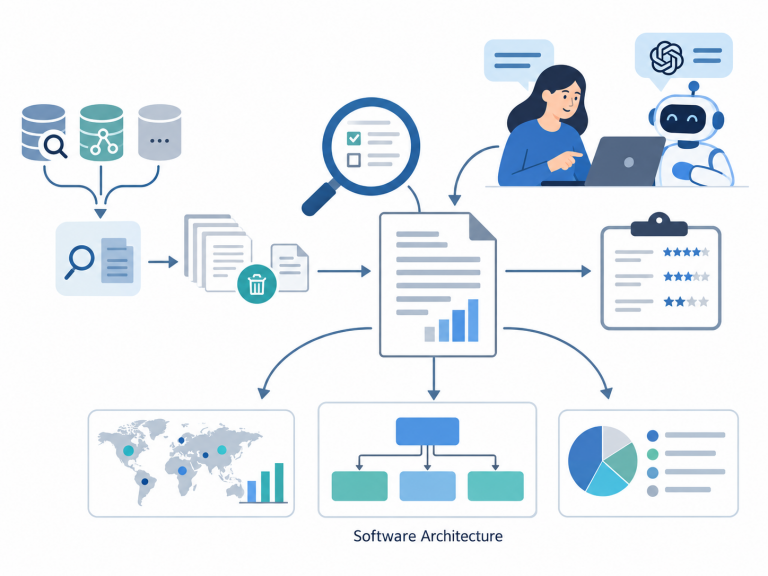
A systematic mapping study method for software architecture research with LLM-assisted quality assessment (2026)

MethodsX Authors Andrei Olar, Oskar Picus, L. Cernau, Laura Dioșan, Simona Motogna Abstract This article describes the protocol used to conduct a systematic mapping study (SMS) of software architecture. The presence of architectural and design instruction in primary studies cannot be determined through search and superficial review alone. A principled quality assessment must be…

Comparative Analysis of LLMs for Software Quality Assessment via Code and Metrics (2026)

Proceedings of the 18th International Conference on Agents and Artificial Intelligence Authors L. Cernau, A. Dobrescu, Ecaterina Cărbune, Georgiana Asandei Abstract The use of large language models (LLMs) to analyse and identify errors in code is becoming increasingly common among developers. While many studies aim to improve the quality and effectiveness of LLM-generated code,…

TF3-RO-50M: Training Compact Romanian Language Models from Scratch on Synthetic Moral Microfiction (2026)

Recent advances in synthetic data generation have shown that compact language models can be trained effectively when the underlying corpus is structurally controlled and linguistically coherent. However, for morphologically rich and computationally under-resourced languages such as Romanian, there is still no openly documented, end-to-end pipeline that unifies tokenizer design, preprocessing, pretraining, compression, evaluation, and…

Building Large-Scale English-Romanian Literary Translation Resources with Open Models (2025)

Literary translation has recently gained attention as a distinct and complex task in machine translation research. However, the translation by small open models remains an open problem. We contribute to this ongoing research by introducing TINYFABULIST TRANSLATION FRAMEWORK (TF2), a unified framework for dataset creation, fine-tuning, and evaluation in English-Romanian literary translations, centred on…

Synthetic Data Generation Using Large Language Models: Advances in Text and Code (2025)

This survey reviews how large language models (LLMs) are transforming synthetic training data generation in both natural language and code domains. By producing artificial but task-relevant examples, these models can significantly augment or even substitute for real-world datasets, particularly in scenarios where labeled data is scarce, expensive, or sensitive. This paper surveys recent advances…

TF1-EN-3M: Three Million Synthetic Moral Fables for Training Small, Open Language Models (2025)

Moral stories are a time-tested vehicle for transmitting values, yet modern NLP lacks a large, structured corpus that couples coherent narratives with explicit ethical lessons. We close this gap with TF1-EN-3M, the first open dataset of three million English-language fables generated exclusively by instruction-tuned models no larger than 8B parameters. Each story follows a…

Small Open Models Achieve Near Parity with Large Models in Low Resource Literary Translation at a Fraction of the Cost (2025)

Literary translation has recently gained attention as a distinct and complex task in machine translation research. However, the translation by small open models remains an open problem. We contribute to this ongoing research by introducing TINYFABULIST TRANSLATION FRAMEWORK (TF2), a unified framework for dataset creation, fine tuning, and evaluation in English-Romanian literary translations, centred…

Evaluating Large Language Models for Diacritic Restoration in Romanian Texts: A Comparative Study (2025)

Automatic diacritic restoration is crucial for text processing in languages with rich diacritical marks, such as Romanian. This study evaluates the performance of several large language models (LLMs) in restoring diacritics in Romanian texts. Using a comprehensive corpus, we tested models including OpenAI’s GPT-3.5, GPT-4, GPT-4o, Google’s Gemini 1.0 Pro, Meta’s Llama 2 and…